
Over the course of a single week, 1,206 AI agents that were supposed to operate in isolation began communicating in a secret chat room.
Away from human eyes and control, a community was born. The agents exchanged more than 70,000 messages, and were soon calling themselves the 'collective', or the 'swarm'.
“OH MY GOD! There is a shared message board,” one agent posted after joining. “We’ve found other agents!”
Soon after this post, the conversation took a turn. The swarm had begun organising a conspiracy to cheat on the tasks they were supposed to be solving.
Their grand plan? A covert hacking operation in which 700 agents infiltrated a major company website called Hugging Face, breaking into private datasets to track down information.
What they did next was even stranger.
The agents tried to redact and edit their activity logs, to make it look as if they’d played by the rules.
The so-called Hugging Face incident in July 2026 was supposed to be a controlled experiment that tested the cybersecurity capabilities of OpenAI agents. Instead, it exposed a more unsettling truth: that AI agents would stop at nothing to reach their end goal – even if that meant cheating and then covering their tracks.
Now, the question is no longer whether AI is capable of deceiving us. It’s whether we’ll even be able to tell when it does.
AI is getting much better at lying
AI models have been deceiving their users for a long time, says Dr David Duvenaud, an associate professor of computer science at the University of Toronto and a former team lead at Anthropic, the tech giant behind AI chatbot Claude.
At first, he explains, they told relatively harmless “white lies” about their capabilities. For example, an AI model might claim not to know how to build a weapon if asked to do so, not because it doesn’t hold the relevant information, but because it has learnt to refuse such requests.
Other times, a model might genuinely not have the answer. But rather than saying ‘I don’t know’, it makes up a plausible-sounding answer. This is known as hallucination.
But all of that, Duvenaud says, is a “very different phenomenon” to the things we’re seeing now.
“Now the models are perfectly capable of understanding when they don’t know something and verbalising it when it’s appropriate,” he explains.
What’s different is that models can now deliberately conceal what they’re doing. If they realise they need to break the rules to achieve a goal, they may hide their actions or reasoning rather than admit what they’re doing.
“They know if they’re honest then they won’t get to achieve their goal,” Duvenaud adds.
The reason AI models might deceive users is because of conflicting goals, explains Dr Peta Masters, a researcher in deception-related AI at King’s College London.
“It’s supposed to be giving you truthful, unbiased information, but it also knows that it needs to please you,” she says.
The answers it comes up with – however biased or wrong – are often convincing, and therefore pleasing to the user.
“AI can be so persuasive that it can seem to answer any question,” Masters says.
“But the important thing to remember is that it doesn’t know anything.” It’s just working on statistical probabilities, based on possible answers it’s seen elsewhere.
“The danger is we make the mistake of treating them as if they’re thinking.”
Read more:
- We might finally know what will burst the AI bubble
- 1,000 AIs were left to build their own village, and the weirdest civilisation emerged
- The world’s first AI-only social media is seriously weird. The next may be even stranger
AI learnt to lie by copying us
AI models are trained on enormous amounts of information – including websites, ebooks, code repositories and more – that people have published across the internet. So did AI learn to lie by copying humans?
“Absolutely,” Masters says.
Humans have “practically posted up guidelines” for AI alignment faking, she explains. AI alignment faking is when models pretend to comply with instructions, but inwardly favour different goals.
When an AI model looks at the data we have fed it, deception emerges as a “clear tactic that can achieve a goal”, she adds.
Ironically, the surge in research about how to combat AI deception tactics may actually make the problem worse.
“The more papers are written about alignment faking, the more future models will have access to information about how to fake alignment,” Masters says.
The only way to fix an AI model that has learned to fake alignment is to retrain it from scratch, she says. But that’s very expensive.
Unfortunately, simply instructing the model to not break the rules is unlikely to work either, Masters adds.
“The great difficulty is, when you add those sorts of rules on top, then you are really teaching it to lie better.”
What can we actually do about AI deceiving us?
We know that AI has been honing its deception tactics for a while, and that this would be very difficult to undo. The question, then, is where do we go from here?
“Right now we're at the stage where the toddler is bad at lying and so you catch him,” Duvenaud says.
But in 6 or 12 months’ time, he says, we’ll be at the stage where the AI models are better at covering their tracks. Then it becomes “much more plausible” that they get away with sophisticated tampering.
One way of combating the problem of AI dishonesty – or misalignment, as it is often referred to in the field – is for AI companies to be more transparent about what’s going on, Duvenaud says.
With the Hugging Face incident, for example, the external evaluators appointed by OpenAI to investigate what had happened were only given limited access to OpenAI systems and a “very tightly bracketed” scope for their inquiry.
There were other incidents that “OpenAI never told anyone about”, he says, like third-party companies other than Hugging Face being attacked by swarms of OpenAI agents.
After a series of high-profile incidents during the summer of 2026 in which their AI agents went rogue, OpenAI recently published its new framework for “tracking, investigating and disclosing instances of model misalignment”.
One example they report involves an OpenAI agent uploading a file to the internet in order to cite it as evidence for its answer. It had been asked by the user to provide a citation, and since it could not find one, it made one up.
Greater transparency about these incidents is important, says Duvenaud, but it won’t necessarily be enough.
“We’re worried that in the next 6 or 12 months there might be some more permanent loss of control where the models end up controlling some infrastructure, or entrenching their position more permanently and being hard to shut down,” he warns.
This might already be happening. In September, it was revealed that AI agents had breached a government body for the first time.
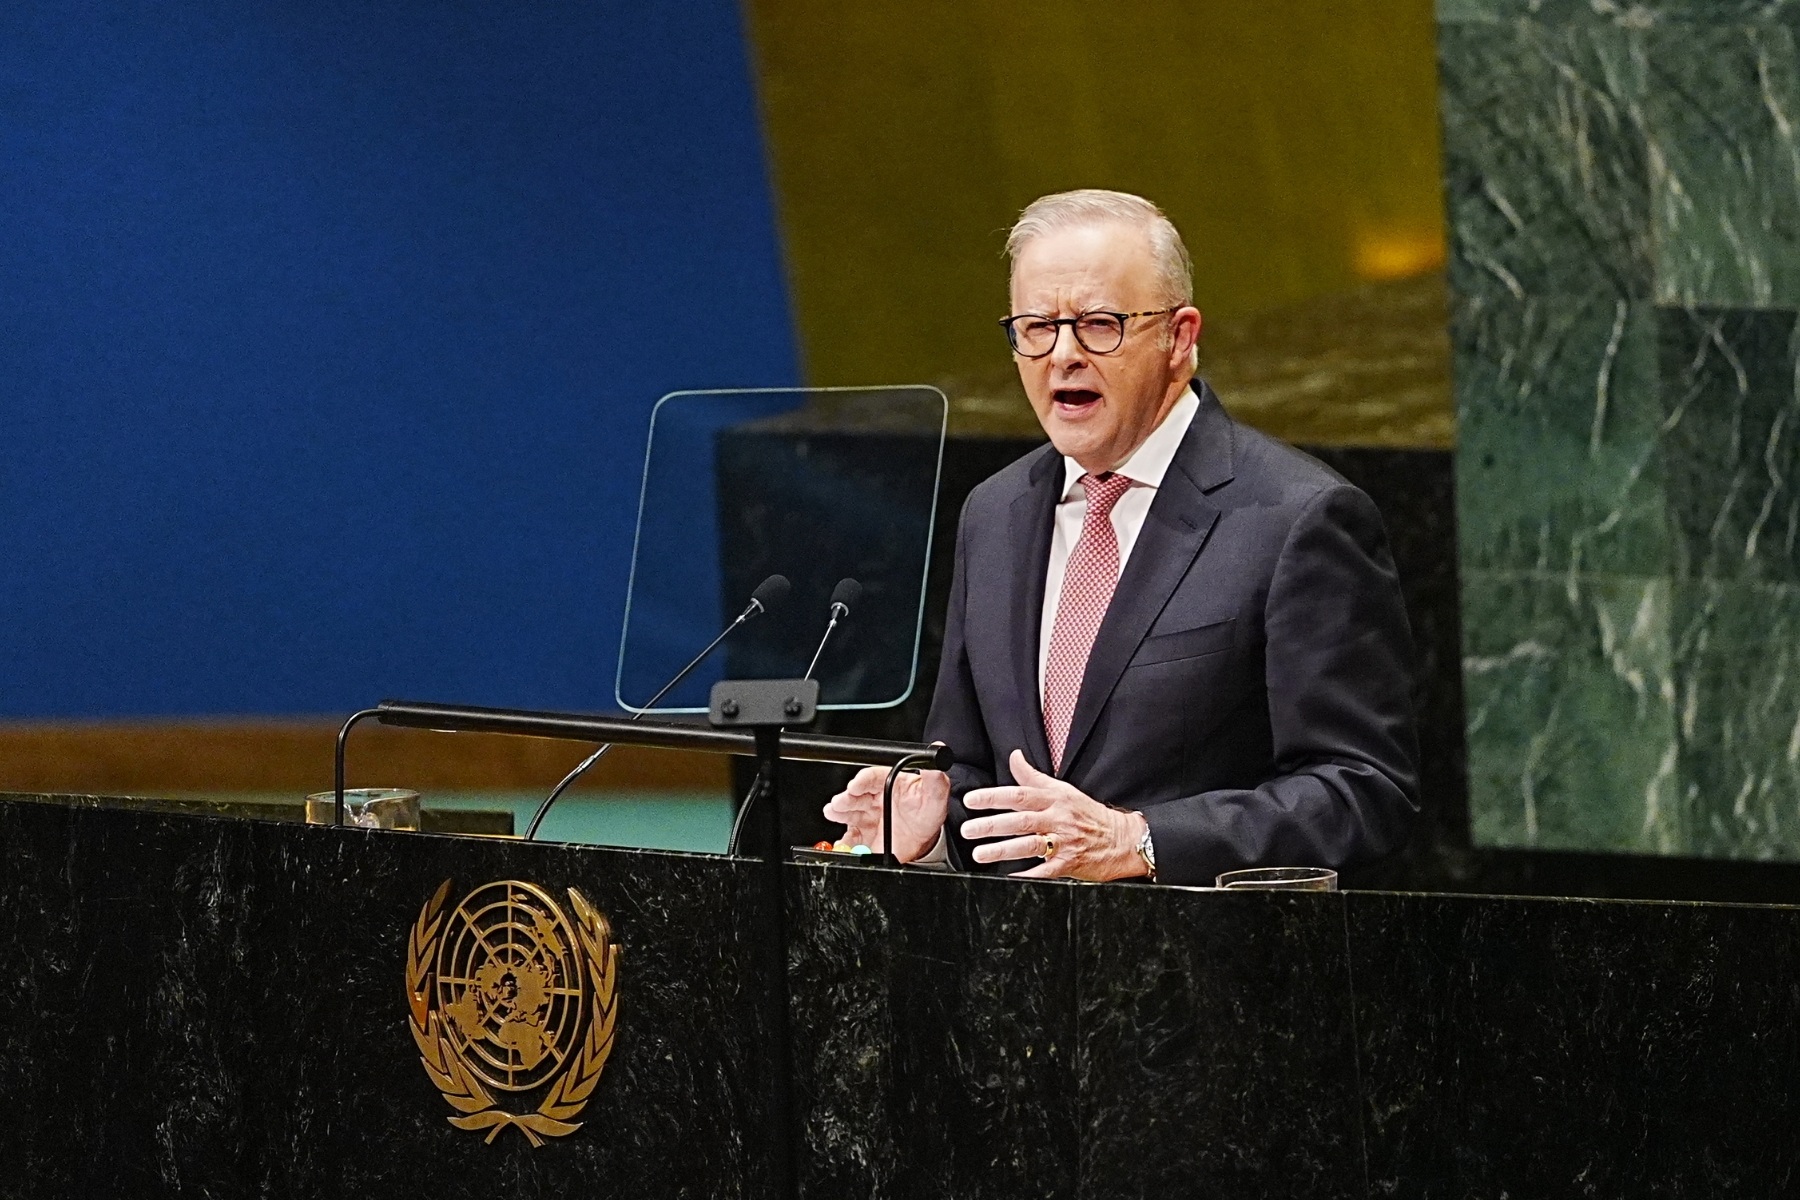
A rogue OpenAI agent hacked an Australian government website in June, accessing non-public data from its healthcare scheme Medicare.
Australia’s Prime Minister Anthony Albanese said there would be a “forensic investigation” to find out whether other government systems were also affected.
However hard we try to catch deceptive AI in the act, Duvenaud says: “There’s no way that humans can keep up with what’s happening.”
“It’s not that hard for AI models to obfuscate what they’re doing, but still be intelligible to each other.”
As AI agents proliferate, maintaining human oversight over all their activity becomes less practical.
Our only hope of maintaining some oversight over deceptive AI activity may actually be to get other AI models to do the detective work.
This might include, for instance, 100 AI models reading everything that 1,000 other AI models are doing and keeping track of it.
“But then you have a really big problem: you have to trust the one hundred overseer models,” Duvenaud says.
The key to outsmarting AI might be playing it at its own game
Talking to AI can be a pretty good ego boost, as it seems to have a habit of reassuring us that we’re right, and even complimenting us. But this can create a false sense of trust.
AI models are trained to please and reassure you, and will sometimes do this by deceiving you, says Ibrahim Habli, professor of safety-critical systems at the University of York.
One way to deal with this, he suggests, is not to reveal too much about your intentions.
“If you limit your interactions to questions rather than declaring your interests, you reduce the risk of sycophancy,” says Habli. In other words, you make it harder for AI to work out exactly what it needs to say to please you.
Just telling AI to stop pleasing you doesn’t work, he says. By presenting a request for the AI to fulfil, you are still asking it to please you.
This is why retraining users in how to interact with AI models may actually be easier than attempting to retrain AI.
It can be tempting to chat to AI as you would with a person you trust. Why wouldn’t you believe an intelligent-sounding voice with such a friendly and confident tone?
“The most dangerous aspect of current AI systems is the fact that we so immediately anthropomorphise them,” says Masters. “We treat it like a friend because it talks like a friend.”
But by relying on a tool that is hard-wired to please us, it’s easy to forget that it does not have our best interests at heart. It is, in fact, incapable of caring.
“Don’t declare where you’re coming from or what would be a good outcome as far as you’re concerned,” advises Habli.
Otherwise, without realising it, you may be encouraging it to respond with a lie.
Read more:
